The claim
Start → Primer → Problem → the results table → Limits. Enough to ask a sharp question in office hours.
Independent high school research · 2026 · a briefing, not a pitch deck
Teach a small network one lesson, then another, then ask about both. Ordinary spike-timing learning wipes the first lesson. Aegis adds a local protect latch and a write budget so the old skill can survive. This page starts from that idea and builds up to the FPGA and the copper board — without assuming you live in hardware.
The board is a harness, not the chip · drag to orbit
00 — How to read this
This is the one-stop briefing for the project. Scroll it like a talk. Jargon is defined the first time it appears. Equations come after the English. Every accuracy number on this page is from the integer Python golden model, not from a programmed FPGA board.
Start → Primer → Problem → the results table → Limits. Enough to ask a sharp question in office hours.
Add How it works, the experiment, Python vs Verilog vs PCB, and the board tour. This is the presentation.
The one-page write-up is the same argument without the lecture. Clone and make experiment to regenerate the table.
01 — Primer, if hardware is not your daily language
You do not need an FPGA course to follow the result. You need these five pictures.
A model that keeps learning after it has already been trained. The failure mode is catastrophic forgetting: lesson two overwrites lesson one. Software methods such as EWC often need a “task ID” — a flag that says “we are now on task 2.” A tiny on-device circuit may not have that oracle.
A spiking neuron adds up incoming current, slowly leaks, and fires a brief pulse when it crosses a threshold (leaky integrate-and-fire, or LIF). Learning here is not gradient descent through layers. It is local: if two neurons fire close together in time, the connection between them gets a little stronger or weaker.
Spike-timing-dependent plasticity. If the input fires just before the output, the synapse strengthens (LTP). If the output fires first, it weakens (LTD). Aegis uses a cheap integer version: bit-shifts instead of exponentials, so an FPGA can do it with a barrel shifter rather than a multiplier farm.
A chip you can reconfigure after manufacturing — a sea of logic blocks you wire up with a hardware description (here, Verilog). The file that actually programs a specific board is a bitstream. This project has Verilog and self-checking tests. It does not yet have a bitstream loaded onto a PYNQ or Arty board.
The golden model is Python: complete, integer, source of every accuracy number. RTL (register-transfer level) is the Verilog circuit that should match that policy. The PCB is a small printed circuit board: power, a motion sensor, connectors. It is a harness that would sit next to an FPGA. It is not the learning chip, and not an ASIC (a custom-manufactured die).
Floating-point math is expensive in LUTs (the FPGA’s building blocks). Aegis stays in fixed-width integers: 8-bit weights, 8-bit protect, power-of-two leaks. If it works in this arithmetic, it is a candidate for a small datapath — that is the point of the project, even before a bitstream exists.
02 — The quiz
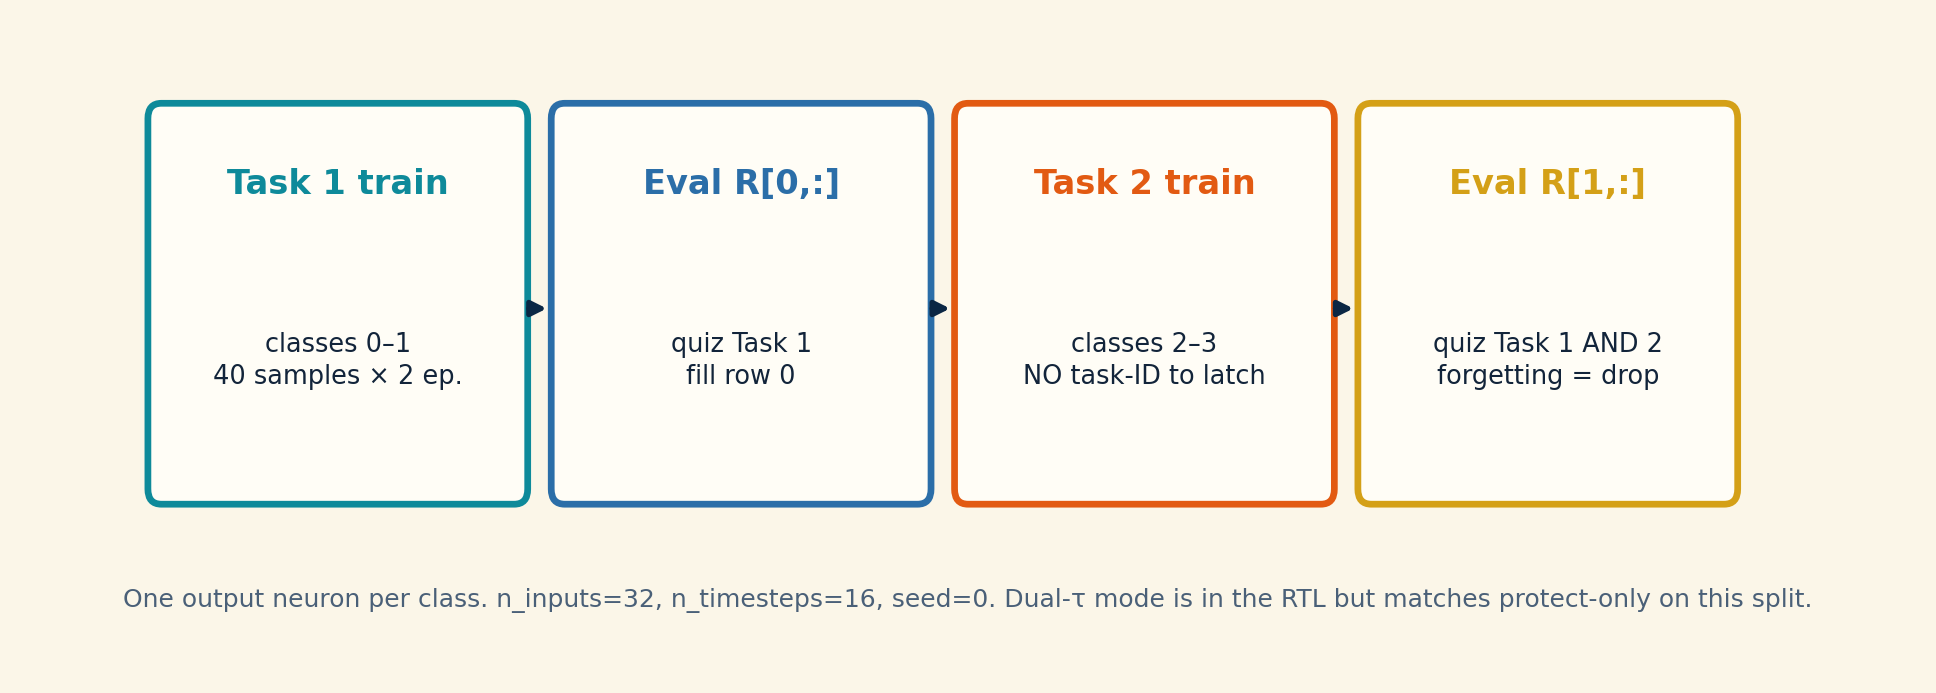
Protocol in one sentence: teach classes 0–1 (Task 1), then classes 2–3 (Task 2), then ask about both. That is class-incremental learning on a tiny split-pattern dataset — a mechanism test, not Split-CIFAR.
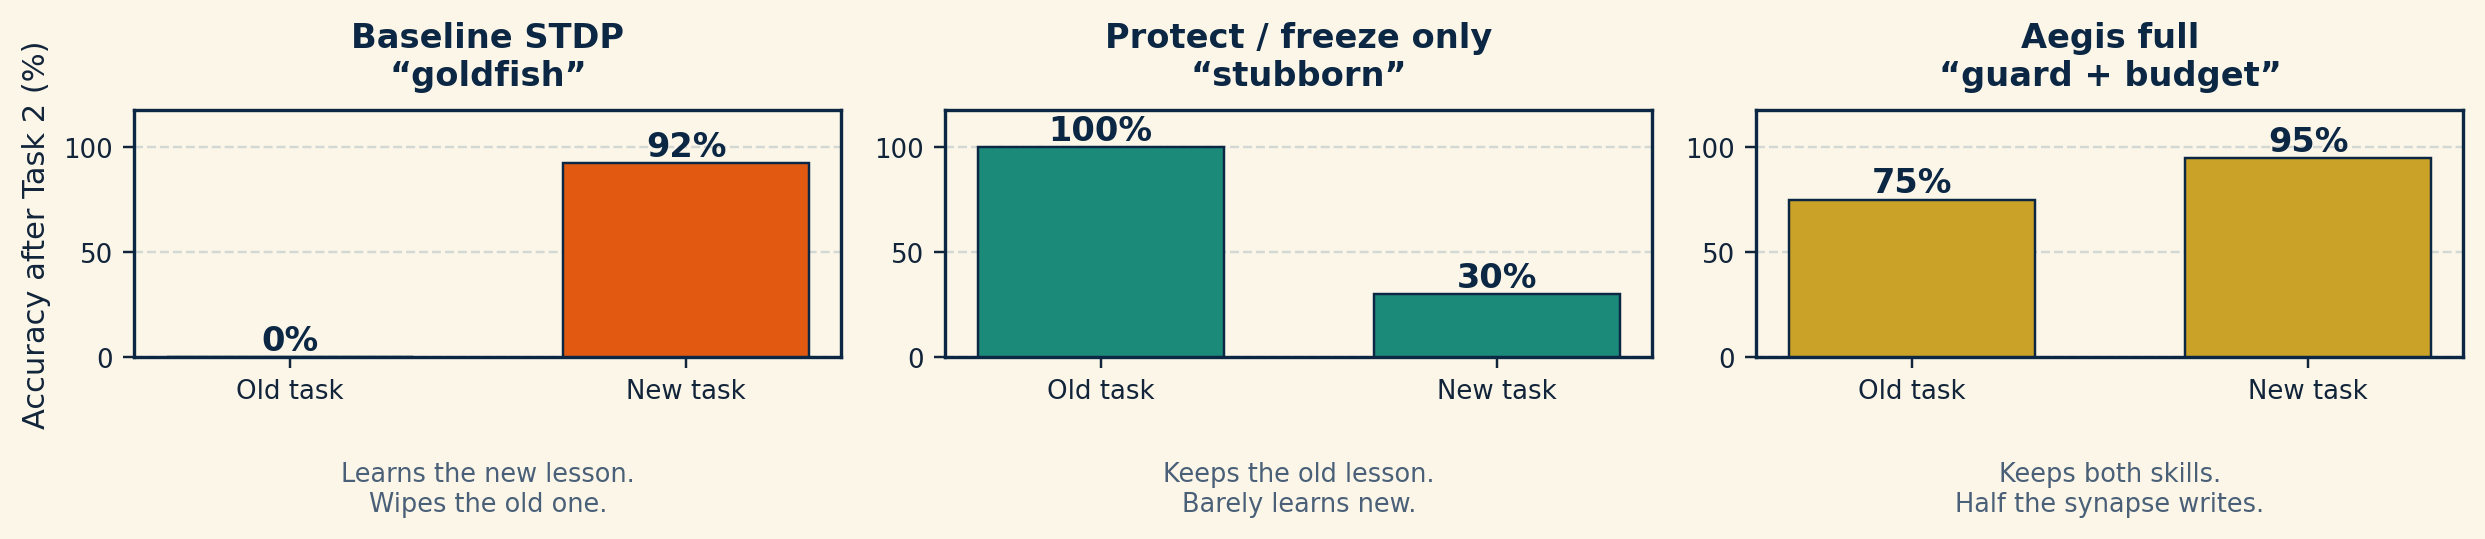
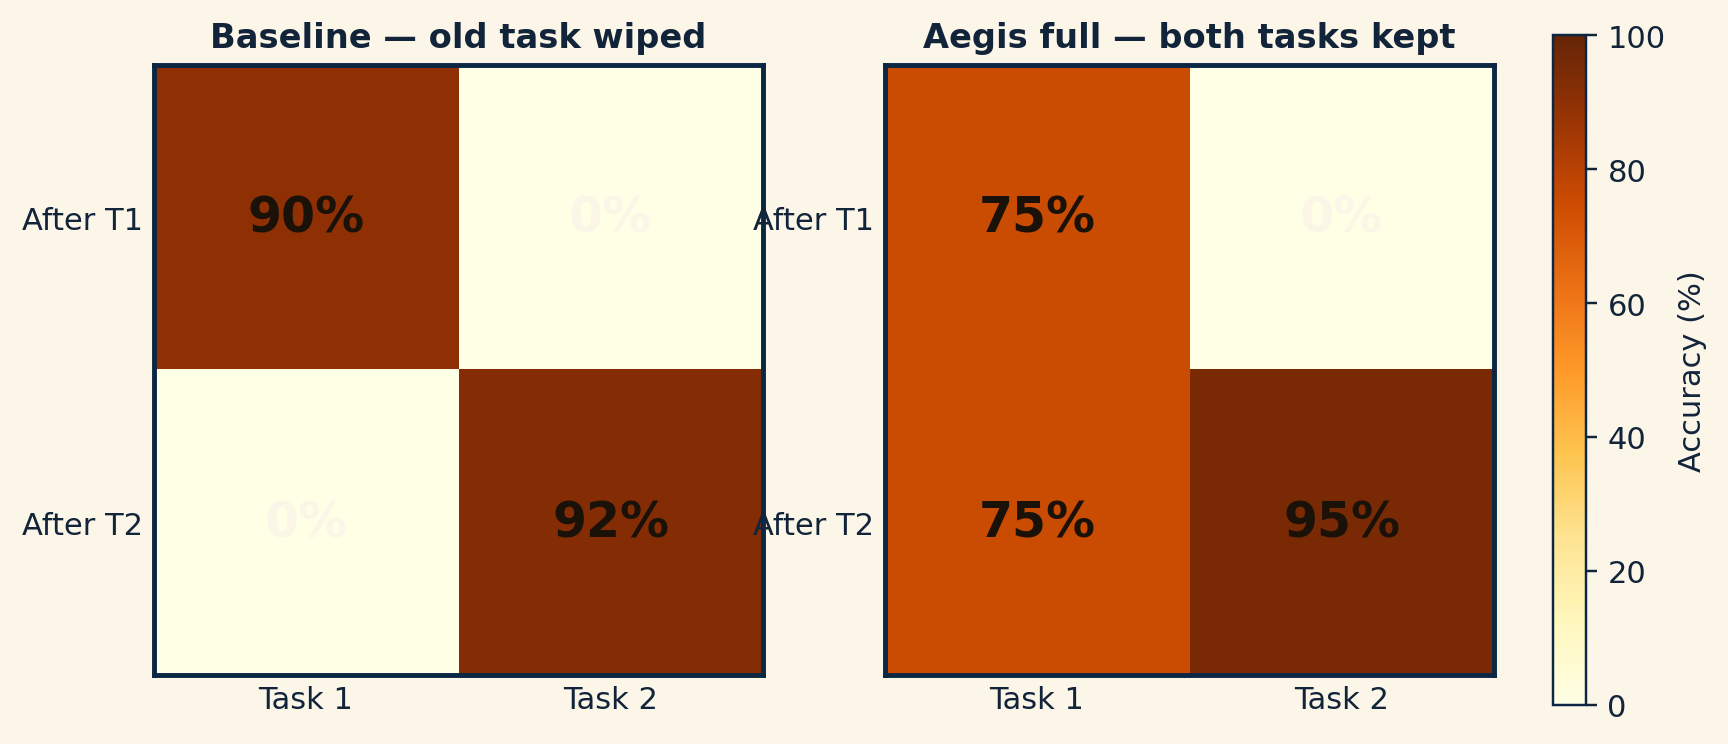
Shift-STDP only. Learns Task 2 by wiping Task 1. 92.5% new, 0% old. Final average 46%. 104k synapse writes.
Latch raises the firing threshold and cuts incoming gain. Keeps 100% of Task 1, starves Task 2 (30%). Final 65%. Stubborn student.
Latch plus write budget. 75% retained, 95% new, forget 0.00, final 85%, 52k writes. The partly-open valve.
03 — The idea
Published FPGA STDP cores make the update cheap. They do not decide what not to overwrite. Software consolidation (EWC and cousins) usually wants task identity and extra Fisher-style memory. Aegis’s bet: a local 8-bit protect latch on each neuron, plus a write budget, is enough to keep an old class while still admitting a new one — with no task-ID pin.
Keep the old task. Learn the new one. Do it with shifts, a local latch, and a write budget — and say clearly what ran in Python versus what exists in Verilog.
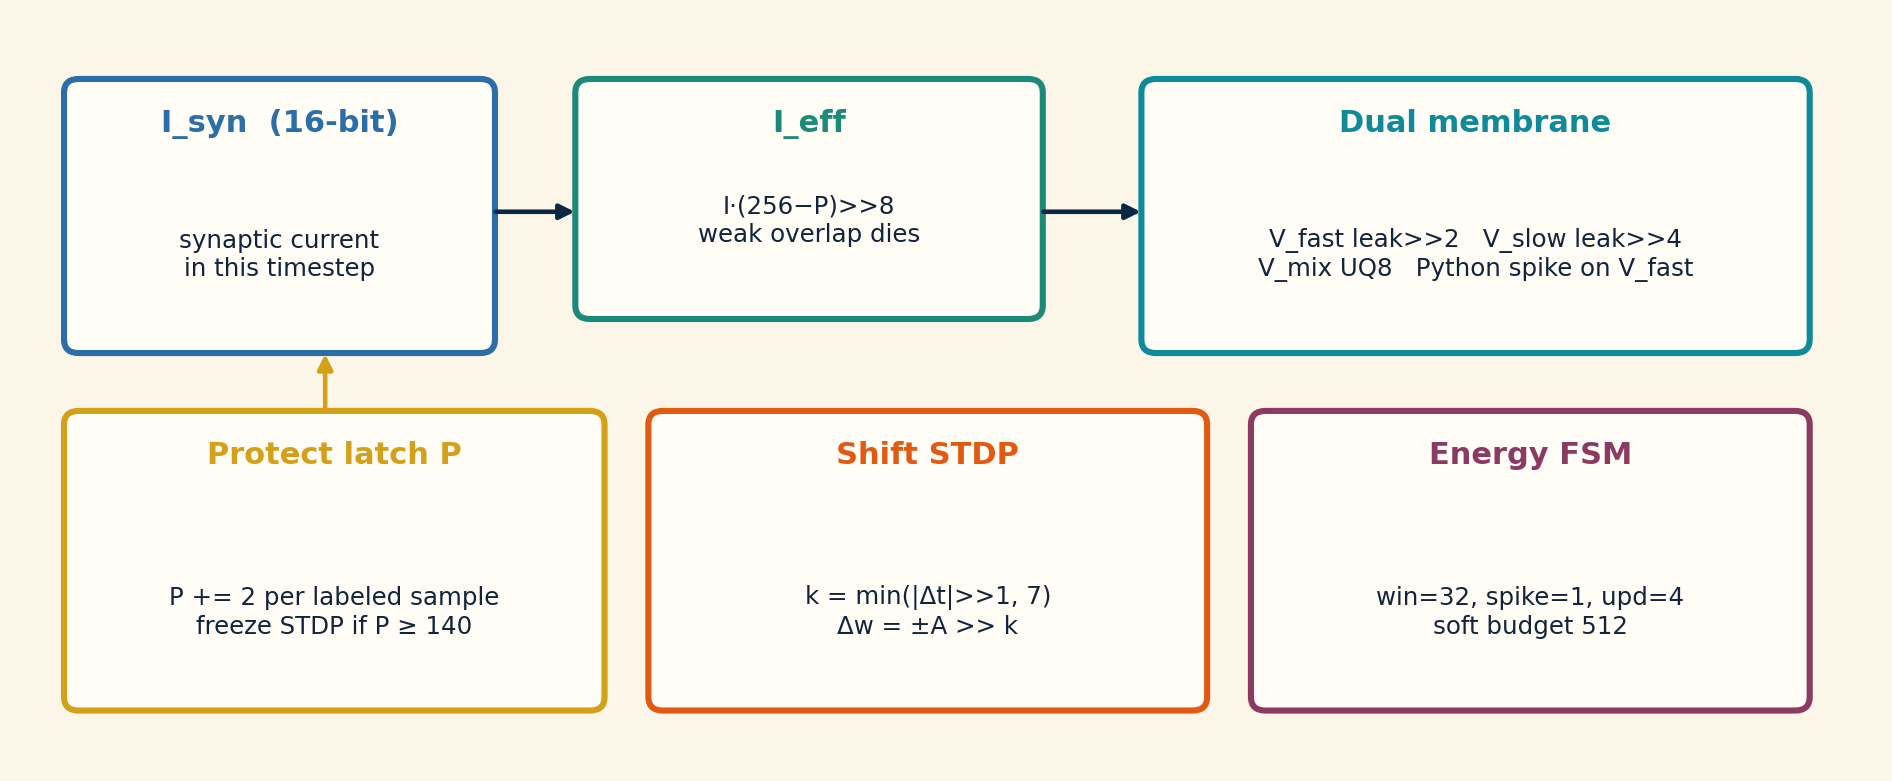
Labeled presentations raise protect P. High P makes that neuron harder to fire and harder to rewrite.
Weak overlap from a new task is attenuated, so old class neurons do not steal the new lesson.
If protect is the only knob, the network becomes the stubborn student. The scheduler is the partly-open valve:
freeze synapses that are already latched or stable; spend the remaining write budget on neurons that still need capacity.
04 — Four blocks
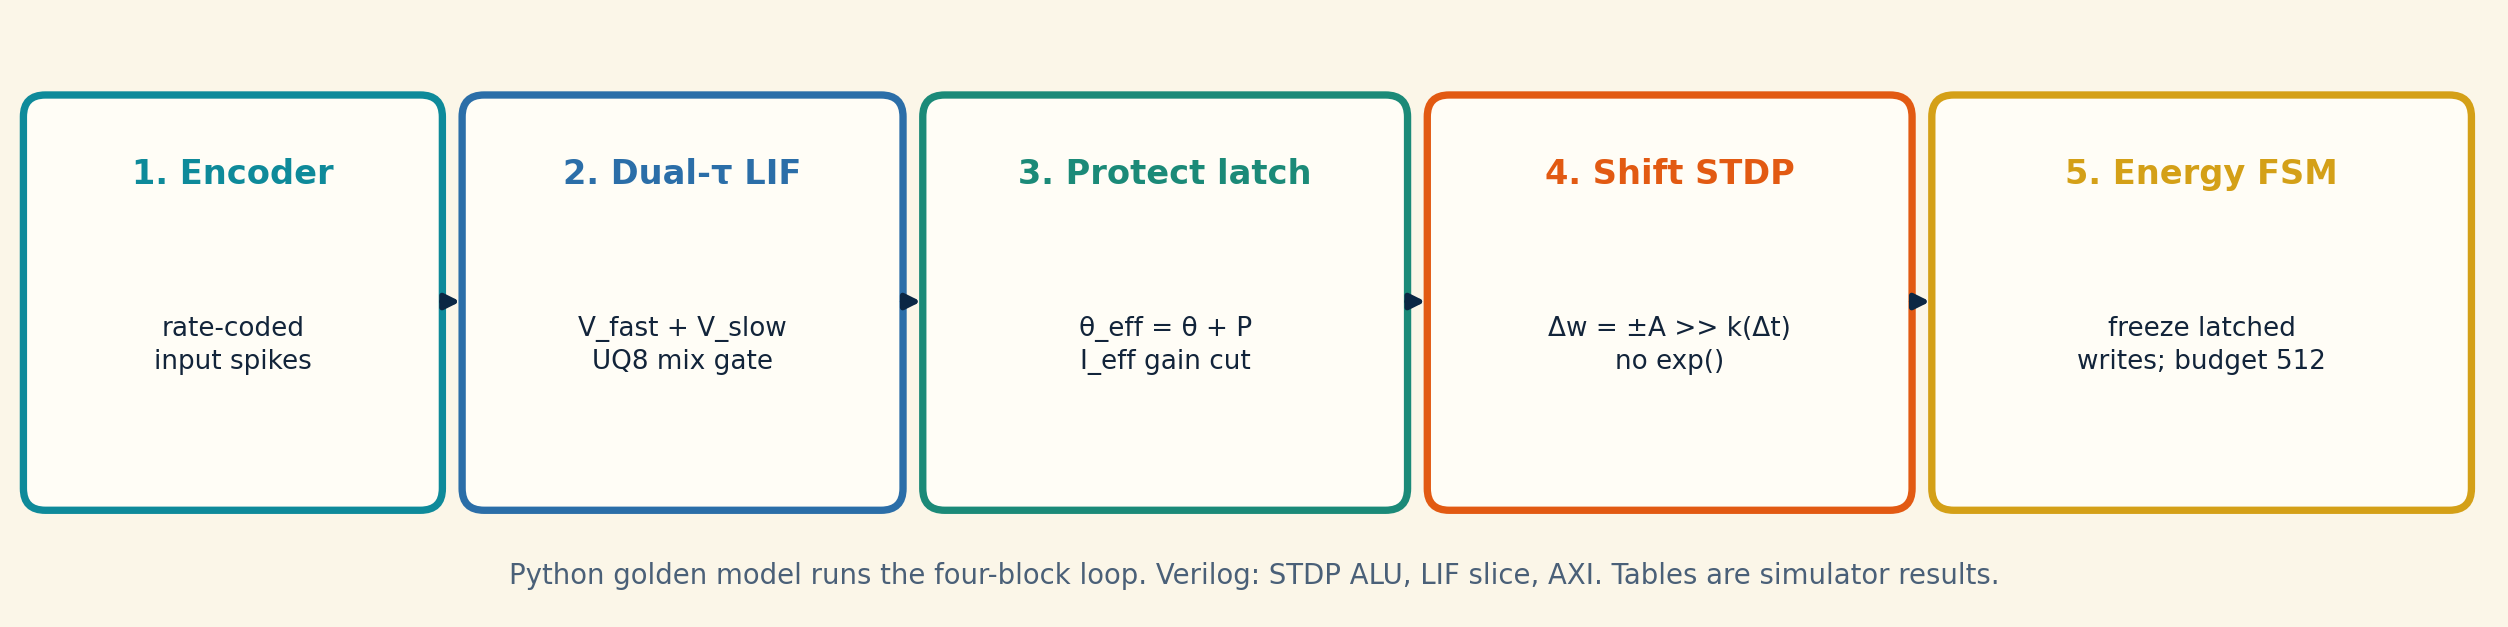
One datapath, four integer blocks. No floating point. No task-ID oracle.
The loop lives in Python and, on a tiny net, in mtstdp_core.
In English
If two spikes are close in time, change the synapse a little. Closer → bigger change. Implemented as a right-shift, so the FPGA needs a shifter, not an exponential. This alone is a goldfish: it learns the latest lesson.
k ← min(|Δt| >>> 1, 7) · Δw ← ± (A >>> k) · A+ = 16, A− = 4
In English
Each labeled sample ticks an 8-bit counter P on the neuron that should own that class. Threshold goes up with P. Incoming current is scaled down. At P ≥ 140 (or stability ≥ 128), STDP freezes. That is the shut valve.
θ_eff = θ + P · I_eff = I · (256 − P) >>> 8 · freeze if P ≥ 140
In English
Two membranes: a fast one that spikes, a slow one meant to hold context. They mix in UQ8. Spikes are decided on the fast membrane, so this experiment does not isolate the slow one — dual-τ matched protect-only on the published split. Claim it after a spike-on-V_mix ablation, not before.
V_fast leak >>> 2 · V_slow leak >>> 4 · spike ← V_fast ≥ θ_eff
In English
A sliding window of 32 ticks. Spikes cost 1, weight updates cost 4, soft budget 512. Over budget, only low-stability, unlatched neurons keep writing. RTL pulses update_req when an STDP accept happens. Write counts in the table are still from the 32-input Python run.
throttled writes counted · latched synapses stay frozen
05 — The experiment
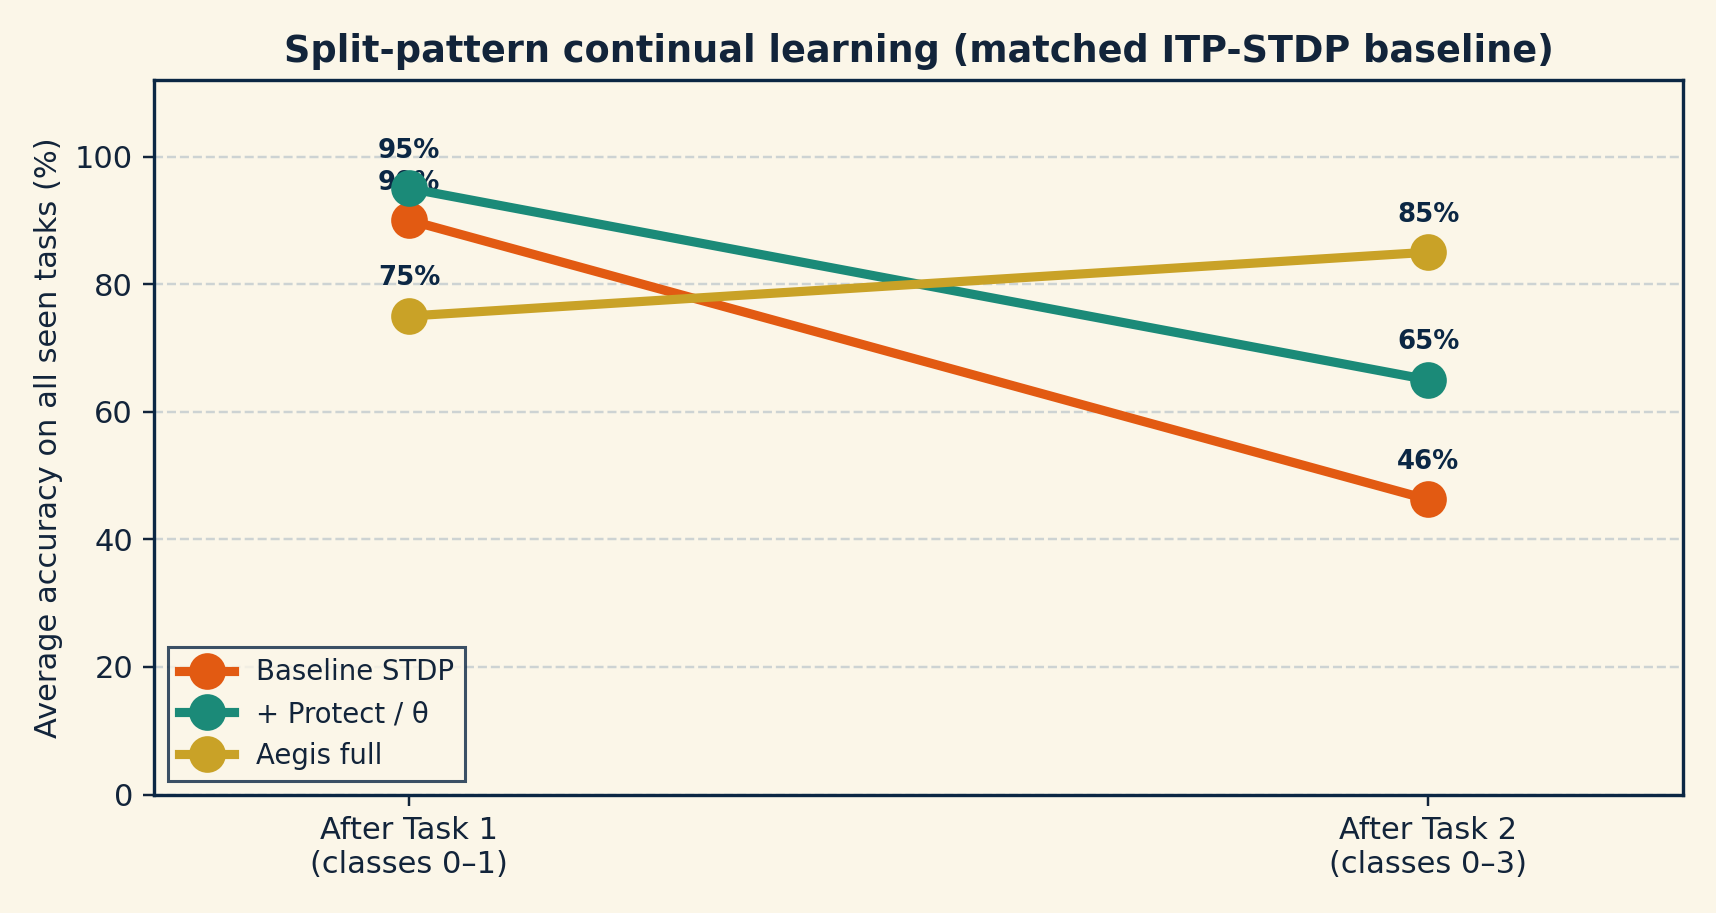
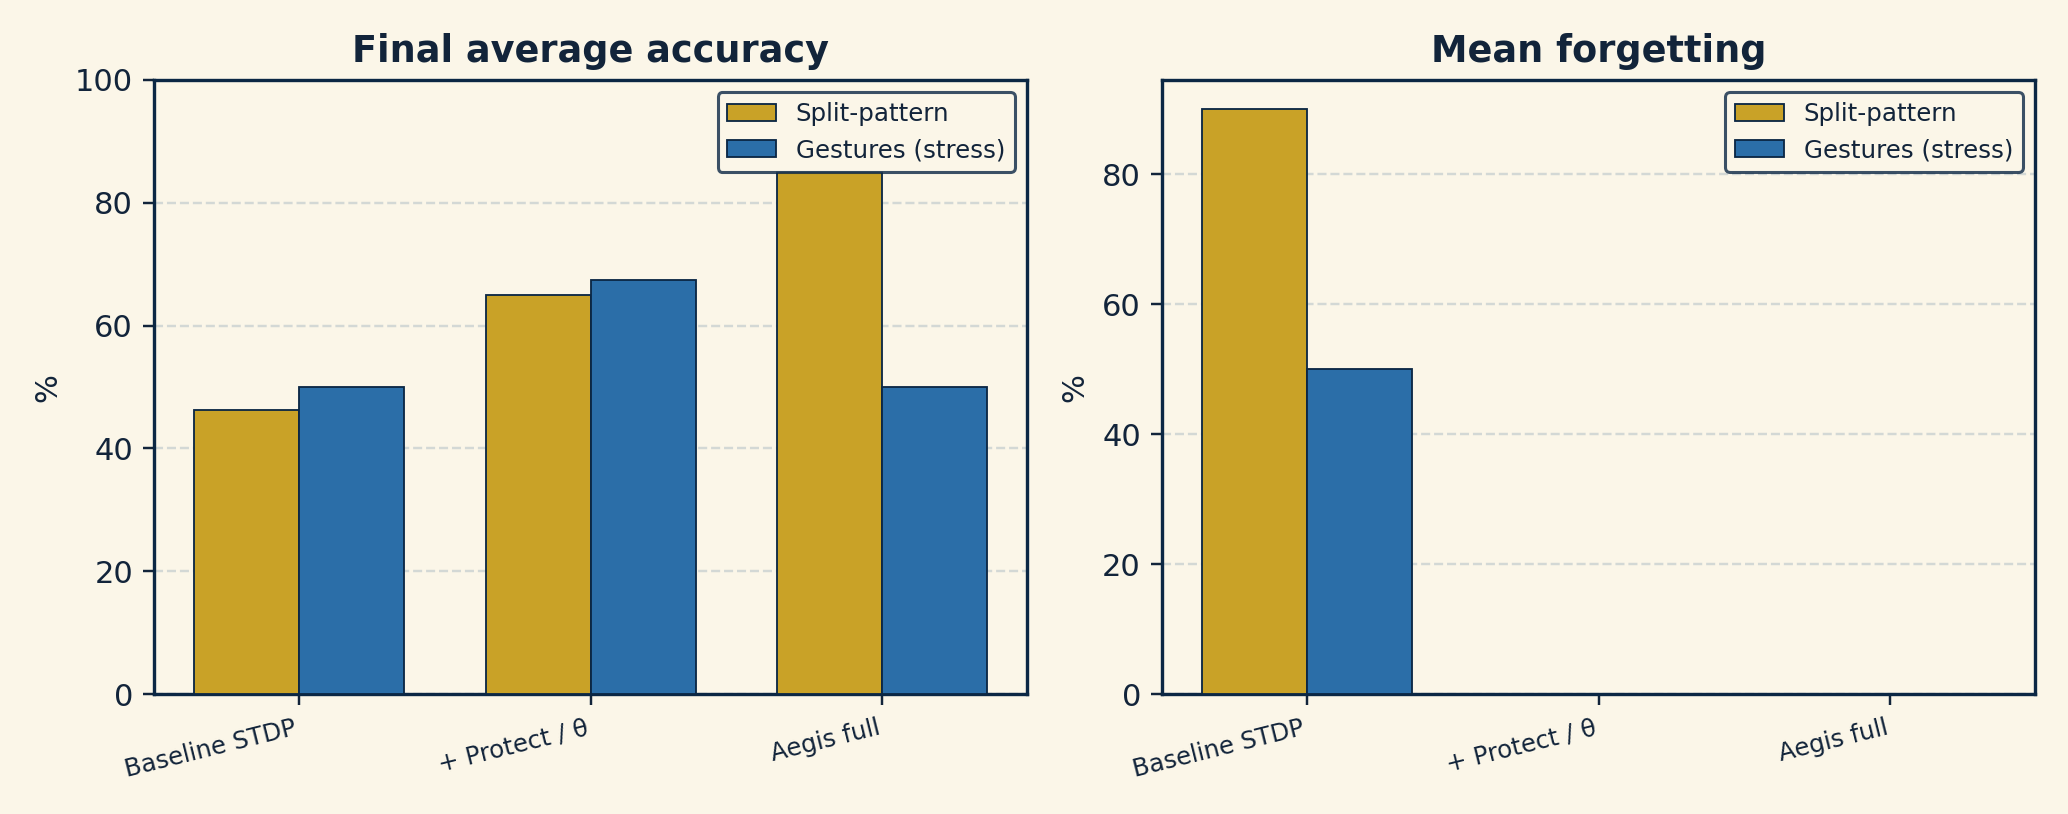
Split-pattern, seed 0: 4 classes, 2 sequential tasks, 40 train / 20 test, 2 epochs, 32 input wires, 16 timesteps, one output neuron per class. Baseline is the same shift-STDP with latch, dual-τ, and scheduler switched off — not a weaker control. After each task the model is tested on every task it has seen. That grid is the R matrix. Forgetting is how much Task 1 drops after Task 2 (Chaudhry-style; the protect-only “−0.05” is Task 1 rising 95% → 100%).
06 — Measurements
These rows are Python simulator measurements of the 32-input protocol. Verilog co-sim is a tiny net (see Stack). Do not read this as FPGA board accuracy.
| Mode | T1 after T1 | T1 after T2 | T2 after T2 | Forget | Writes |
|---|---|---|---|---|---|
| Baseline STDP | 90% | 0% | 92.5% | 0.90 | 104,311 |
| + Protect / θ | 95% | 100% | 30% | −0.05 | 73,803 |
| + Dual τ | 95% | 100% | 30% | −0.05 | 73,803 |
| Aegis full | 75% | 75% | 95% | 0.00 | 52,059 |
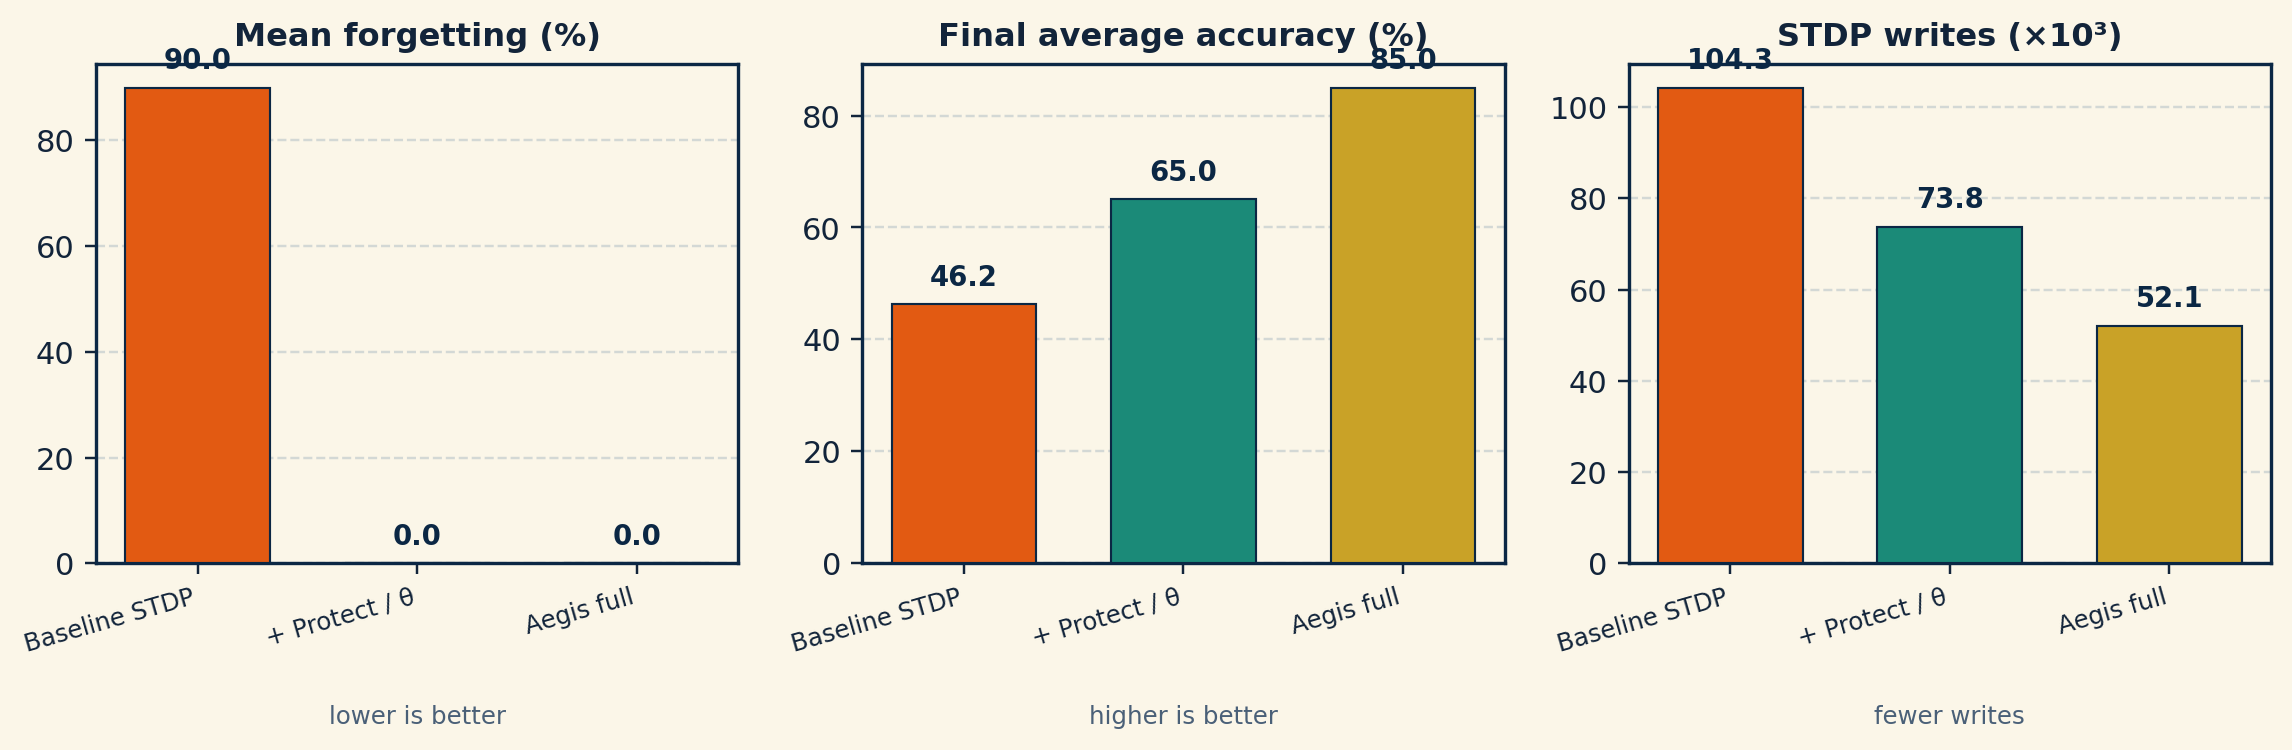
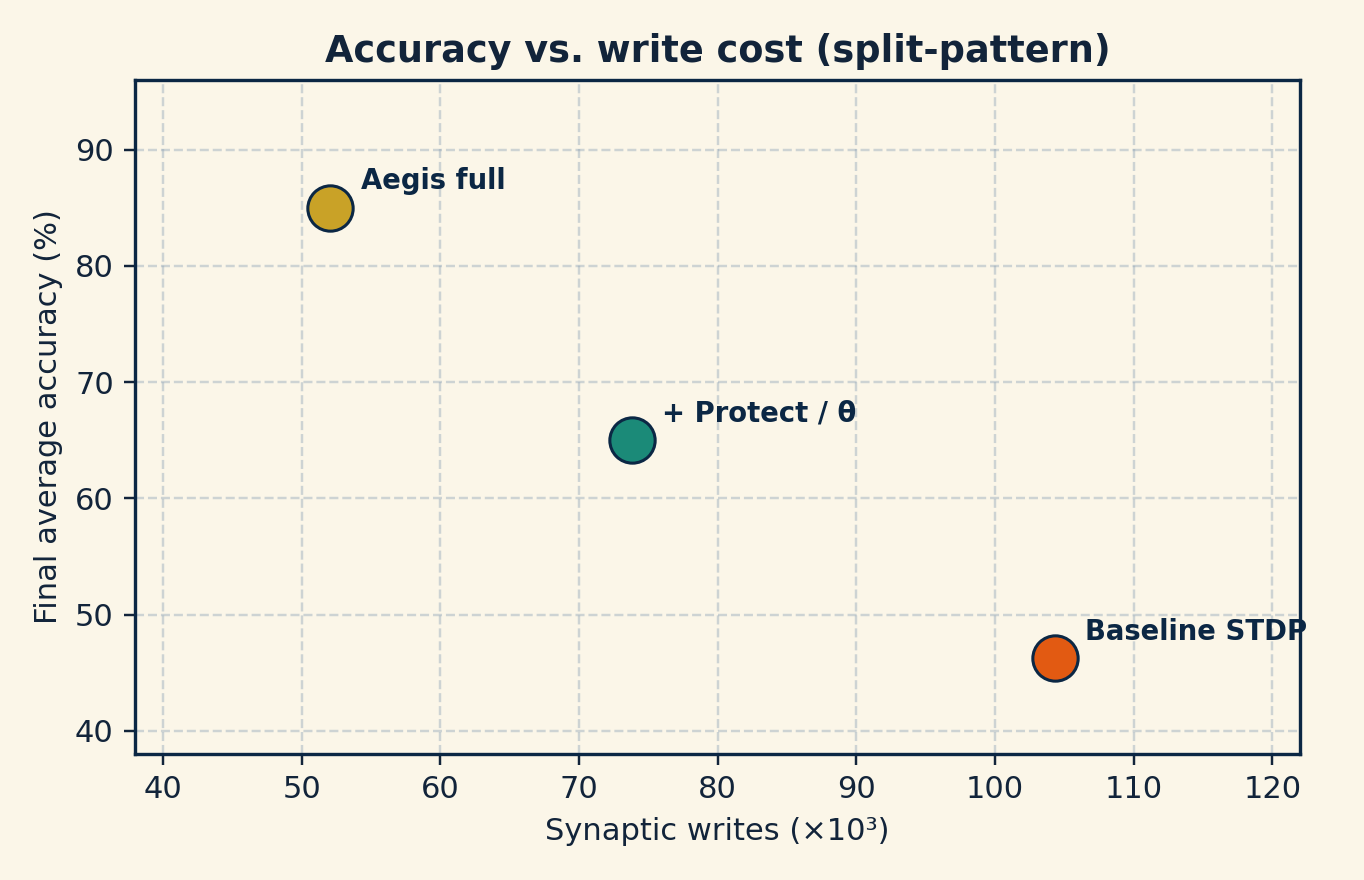
Final average 85% vs 46%, at half the synaptic writes.
Protect-only is stubborn. Full Aegis is the partly-open valve.
Dual-τ is identical to protect-only on this split — spikes on V_fast, so the slow membrane is not isolated.
07 — What was actually built
Think of the project as a stack, not a chip. The science claim is in software. The circuit claim is “this policy fits in Verilog and matches on a tiny net.” The board claim is “a legal, DRC-clean harness exists for IMU + power.”
python/mtstdp — integer network, split-pattern protocol, ablation. Config is the single source of bit widths, leaks, latch, and budget. Run make experiment.
rtl/mtstdp_core.v — STDP ALU, LIF slice, protect increment, LTD/contrast, scheduler, AXI-Lite weight readback. Co-sim: LTP 40→56, LTD 40→36, protect +2. Output winner-take-all is simultaneous in Python and sequential in RTL. Icarus tests pass. No bitstream on hardware.
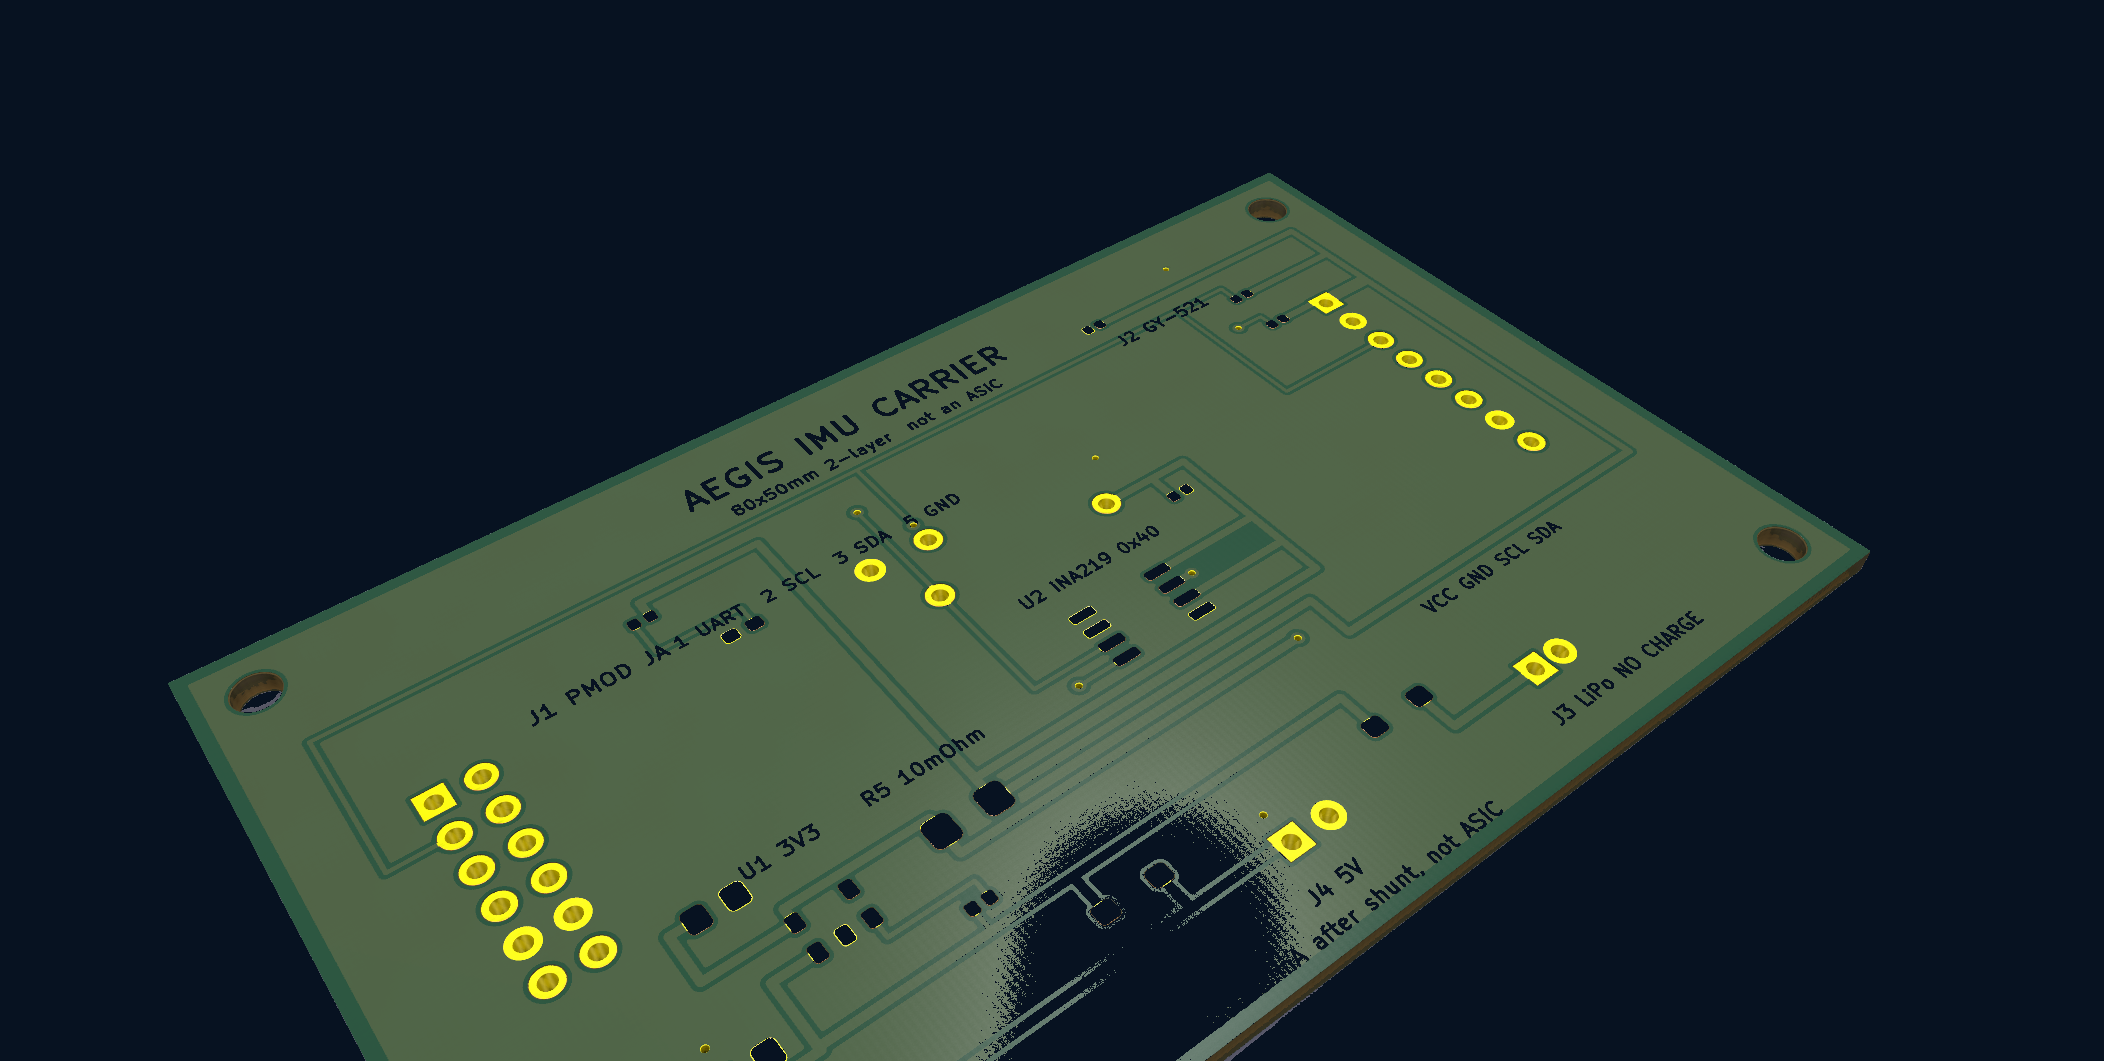
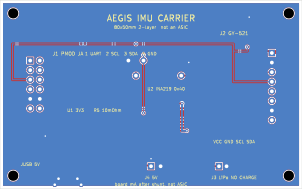
PMOD to an FPGA board, GY-521 motion sensor, USB or discharge-only LiPo, 3.3 V regulator, current sense. ERC 0, DRC 0. Board current is not chip milliwatts. J3 is not a charger.
| Mechanism | Python golden model | Checked-in RTL |
|---|---|---|
| STDP ALU ±A >> k | Yes | Yes |
| Spike compare | V_fast | V_fast |
| Protect increment | +2 per labeled sample | i_sample_end |
| LTD write | Yes | ST_LTD |
| Scheduler on STDP | stability > 64 over budget | update_req pulsed |
| 32-input accuracy table | Yes — this is the result | Not on a board |
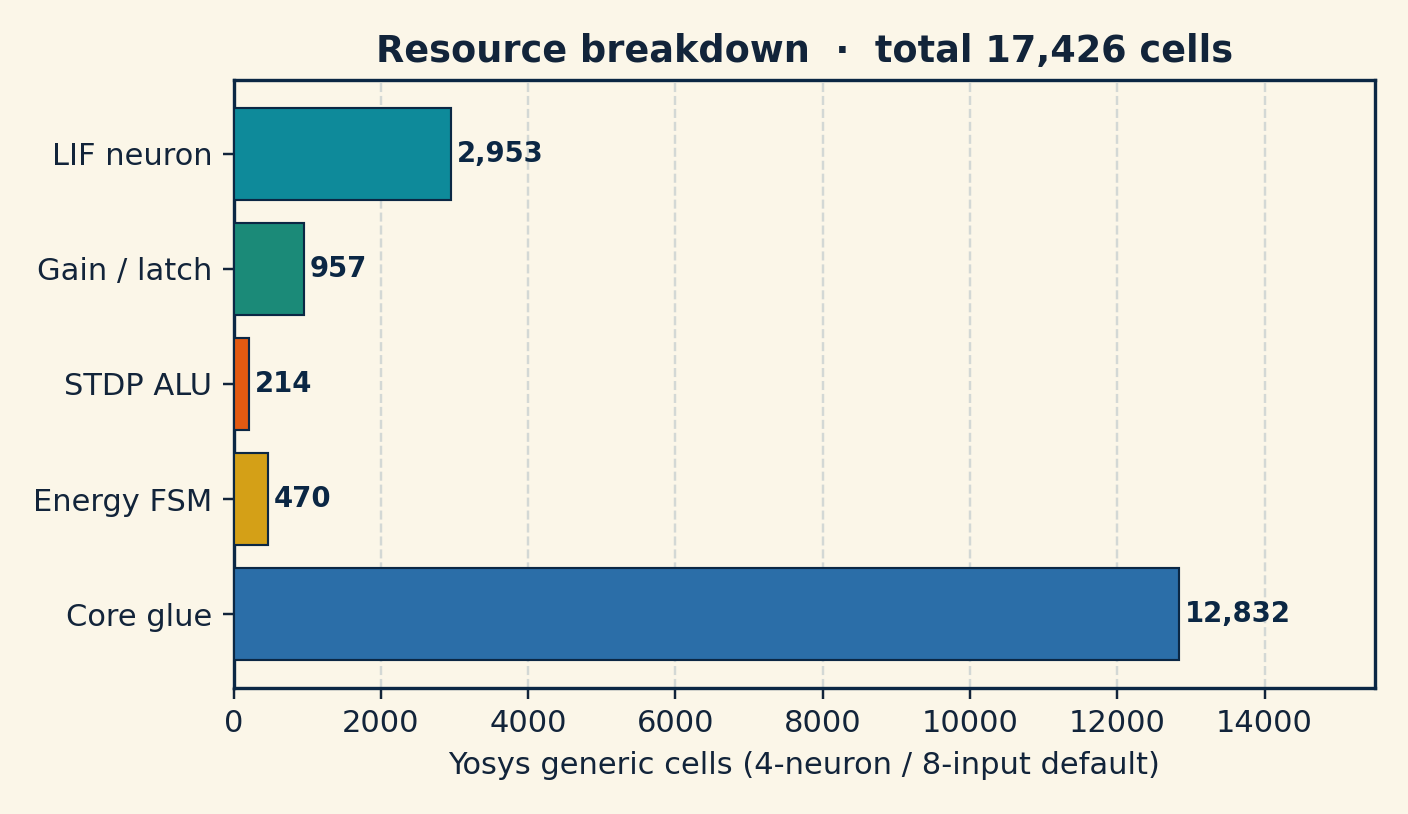
Verilog describes gates and registers. A simulator (Icarus) checks that description against test vectors.
Yosys maps it to generic cells so you can see size, not to a finished bitstream.
Constraints files (fpga/constraints/) say which physical pins on a PYNQ-Z2 or Arty A7 would carry UART and I²C
if you later generate a bitstream in Vivado. That last step is future work. Until then, “FPGA core” means
synthesizable RTL + tests, not a blinking board running the 32-input protocol.
08 — The copper, in English
Why a board at all? An on-device learner needs a sensor and a power story. This 2-layer FR4 carrier is that story: plug into Digilent PMOD JA, talk to a GY-521 IMU over I²C, sip 5 V from USB or a LiPo pack, regulate to 3.3 V, measure board current with a shunt and an INA219. Custom footprints show copper and silk, not molded 3D packages.
The ribbon to the FPGA board. Digilent JA pinout: UART and I²C so the FPGA (once programmed) can talk to the IMU and a host.
A cheap 6-axis motion sensor (MPU-6050 class). Accelerometer + gyro. The “gesture” dataset is synthetic IMU-like codes, not live captures from this part — yet.
USB Micro-B 5 V, Schottky-ORed with a JST-PH LiPo connector. J3 is discharge only — no charge IC. Do not treat it as a charger.
AP2112K-3.3 regulator. 10 mΩ shunt. INA219 current/voltage monitor at I²C address 0x40. That current is the board, not the milliwatts of a learning ASIC.
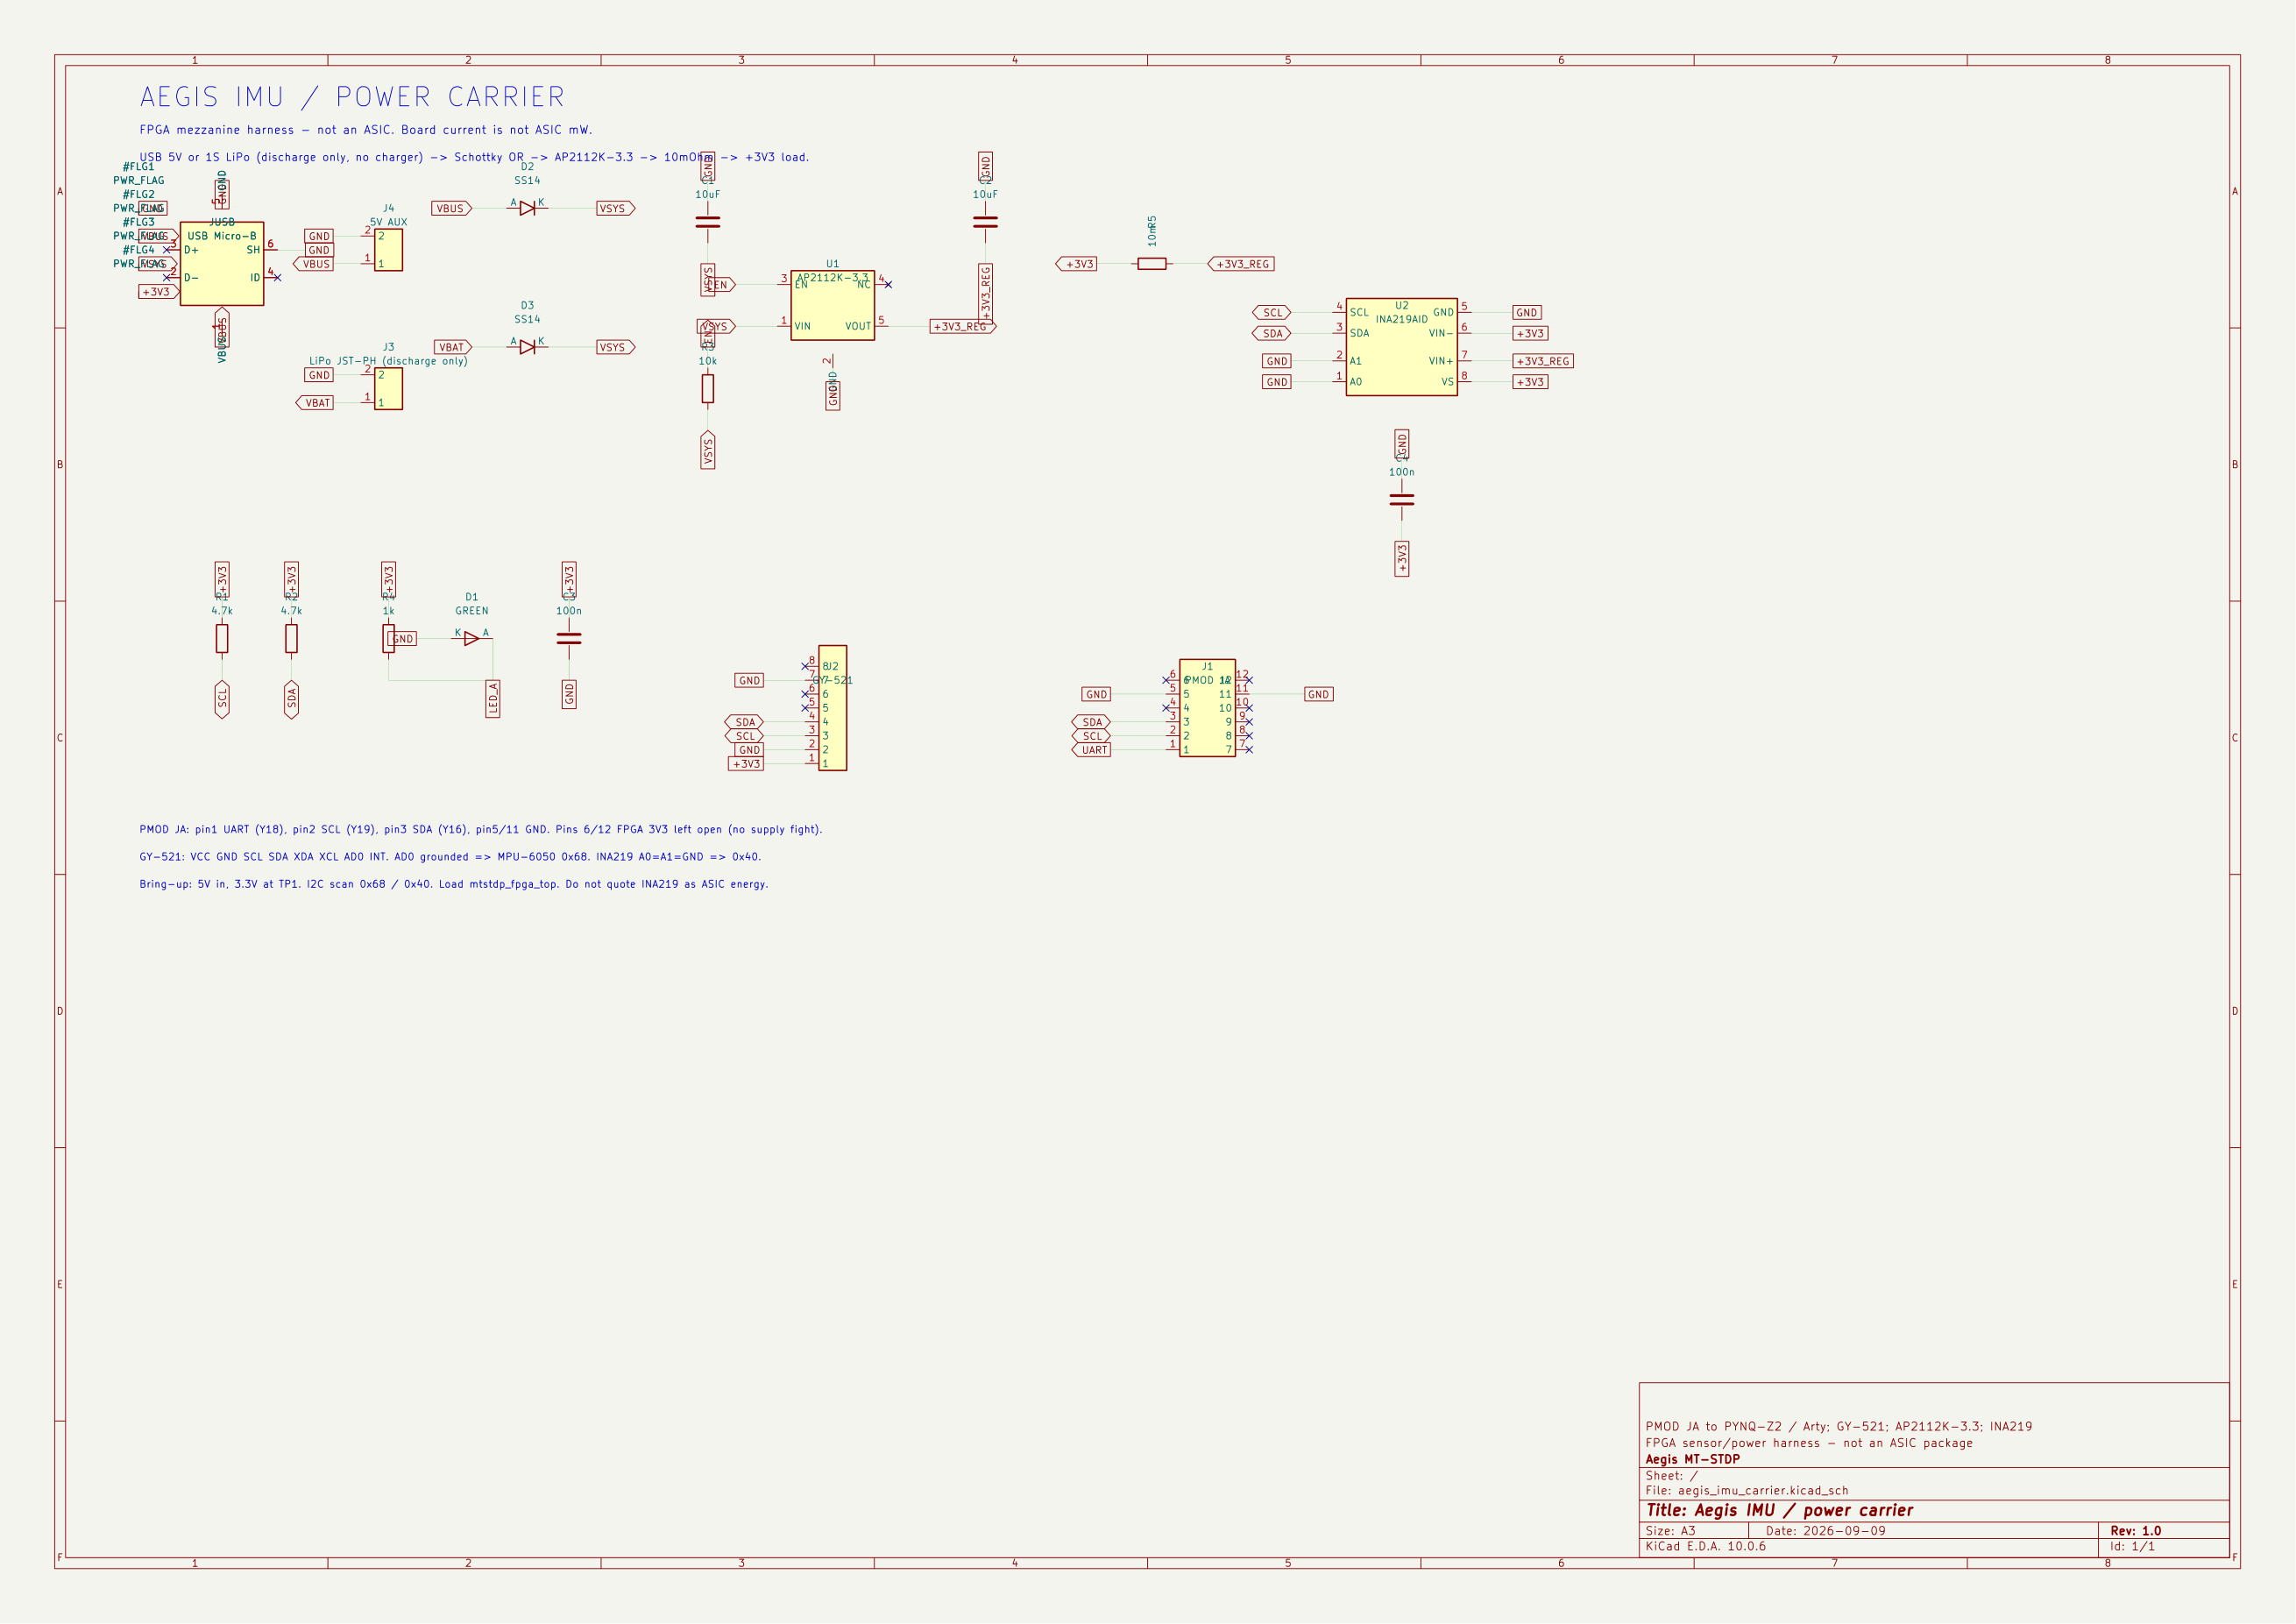
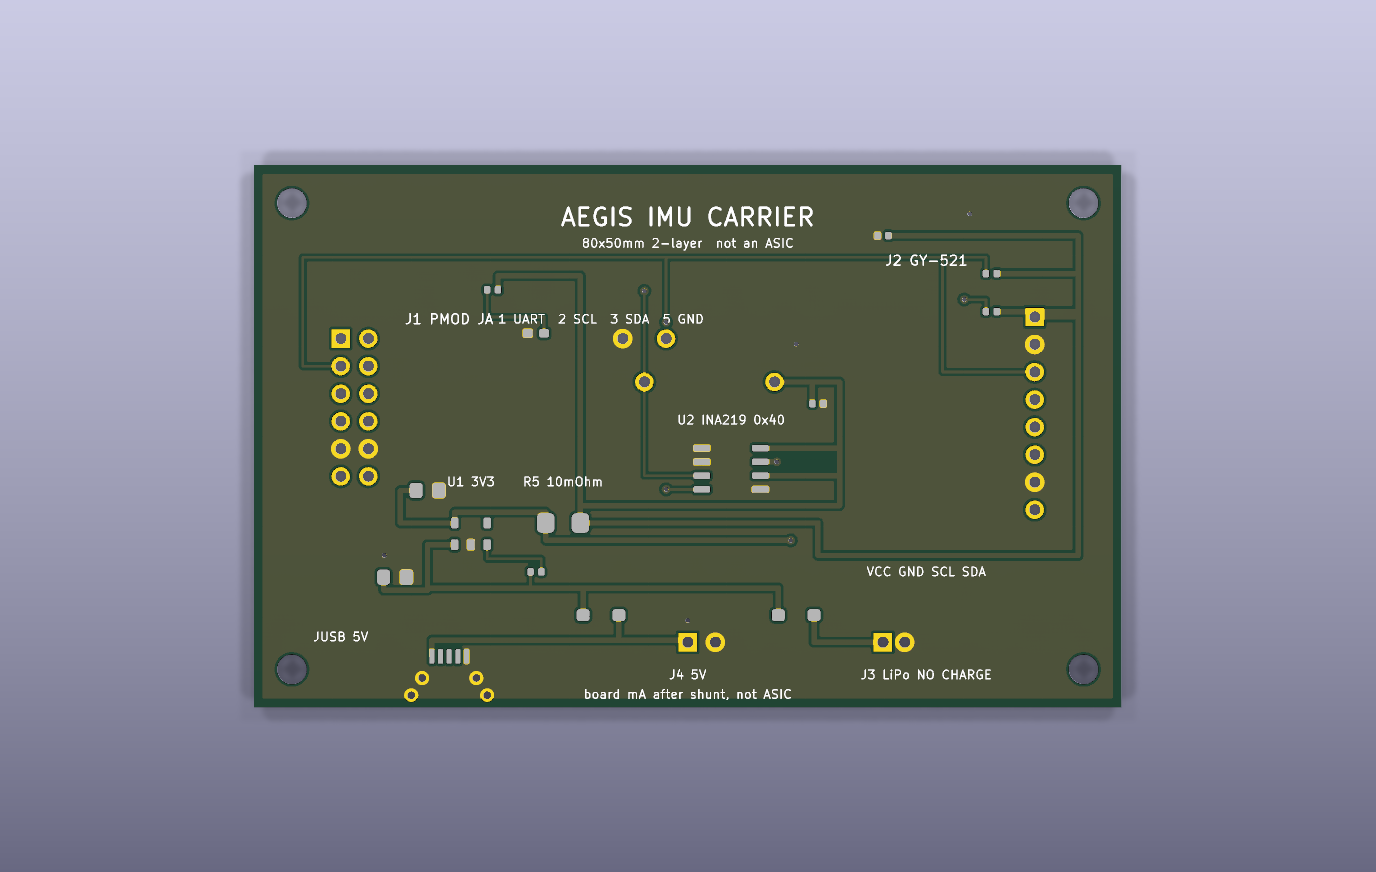
pcb/gerbers/. KiCad 10, ERC 0, DRC 0.09 — What this is not
French 1999 (catastrophic forgetting). Kirkpatrick et al. 2017 (EWC — task-aware, extra memory). Diehl & Cook 2015 (unsupervised STDP in software). Davies et al. 2018 (Intel Loihi — a neuromorphic chip this project is not). FPGA STDP literature typically accelerates the update; Aegis’s claim is the protect + budget policy on integer STDP.
10 — Conclusions
The scientific claim is a mechanism, not a leaderboard. On this integer split-pattern run, a local protect latch without a write budget keeps the old task and barely learns the new one. Adding a write budget is what opens the valve far enough to learn Task 2 while still holding most of Task 1 — 85% vs 46% final average, at about half the synapse writes. Dual-τ did not earn a separate claim. Overlapping gesture codes can reverse the ranking. Accuracy is Python. Verilog is a tiny-net co-sim. The copper board is a harness.
Matched shift-STDP learns the new task and drops the old one to 0%. A core that only accelerates that update inherits the amnesia.
The latch keeps Task 1. The scheduler is what still admits Task 2. The interesting point is the partly-open valve, not the freeze.
A local integer continual-learning policy for power-of-two STDP — protect plus write budget, no task-ID oracle — measured in a golden model, with RTL that closes the same loop on a tiny net, and a DRC-clean IMU/power carrier. Not a bitstream, not an ASIC, not Split-CIFAR.
11 — Reproduce
Python 3.10+, Icarus Verilog for RTL tests, Yosys optional, KiCad 10 optional. One-page narrative: write-up. Repo: github.com/krishharma/aegis-mtstdp.
python3 -m pip install -r requirements.txt
make pytest
make sim
make experiment
python3 -m http.server 8766 --directory webpython/mtstdp — config is the single source of widths, leaks, latch, and budget. This is the accuracy table.
rtl/ + tb/ — ALU, LIF, protect/LTD/scheduler FSM, AXI-Lite, tiny-net co-sim. Not a bitstream.
pcb/ — schematic, routed board, Gerbers, GLB, STEP. Not GDS. Generator: pcb/gen_kicad.py.